AI Agent with Business Guardrails
Catalog Enrichment Agent
A catalog with thousands of items does not enter the platform through the front door. It enters through a spreadsheet with truncated descriptions, the supplier code where the name should be, and a folder of photos taken at the counter. The work of turning that into a catalog that sells is real, it is large, and it is why so many B2B digital projects stall before going live.
What it is
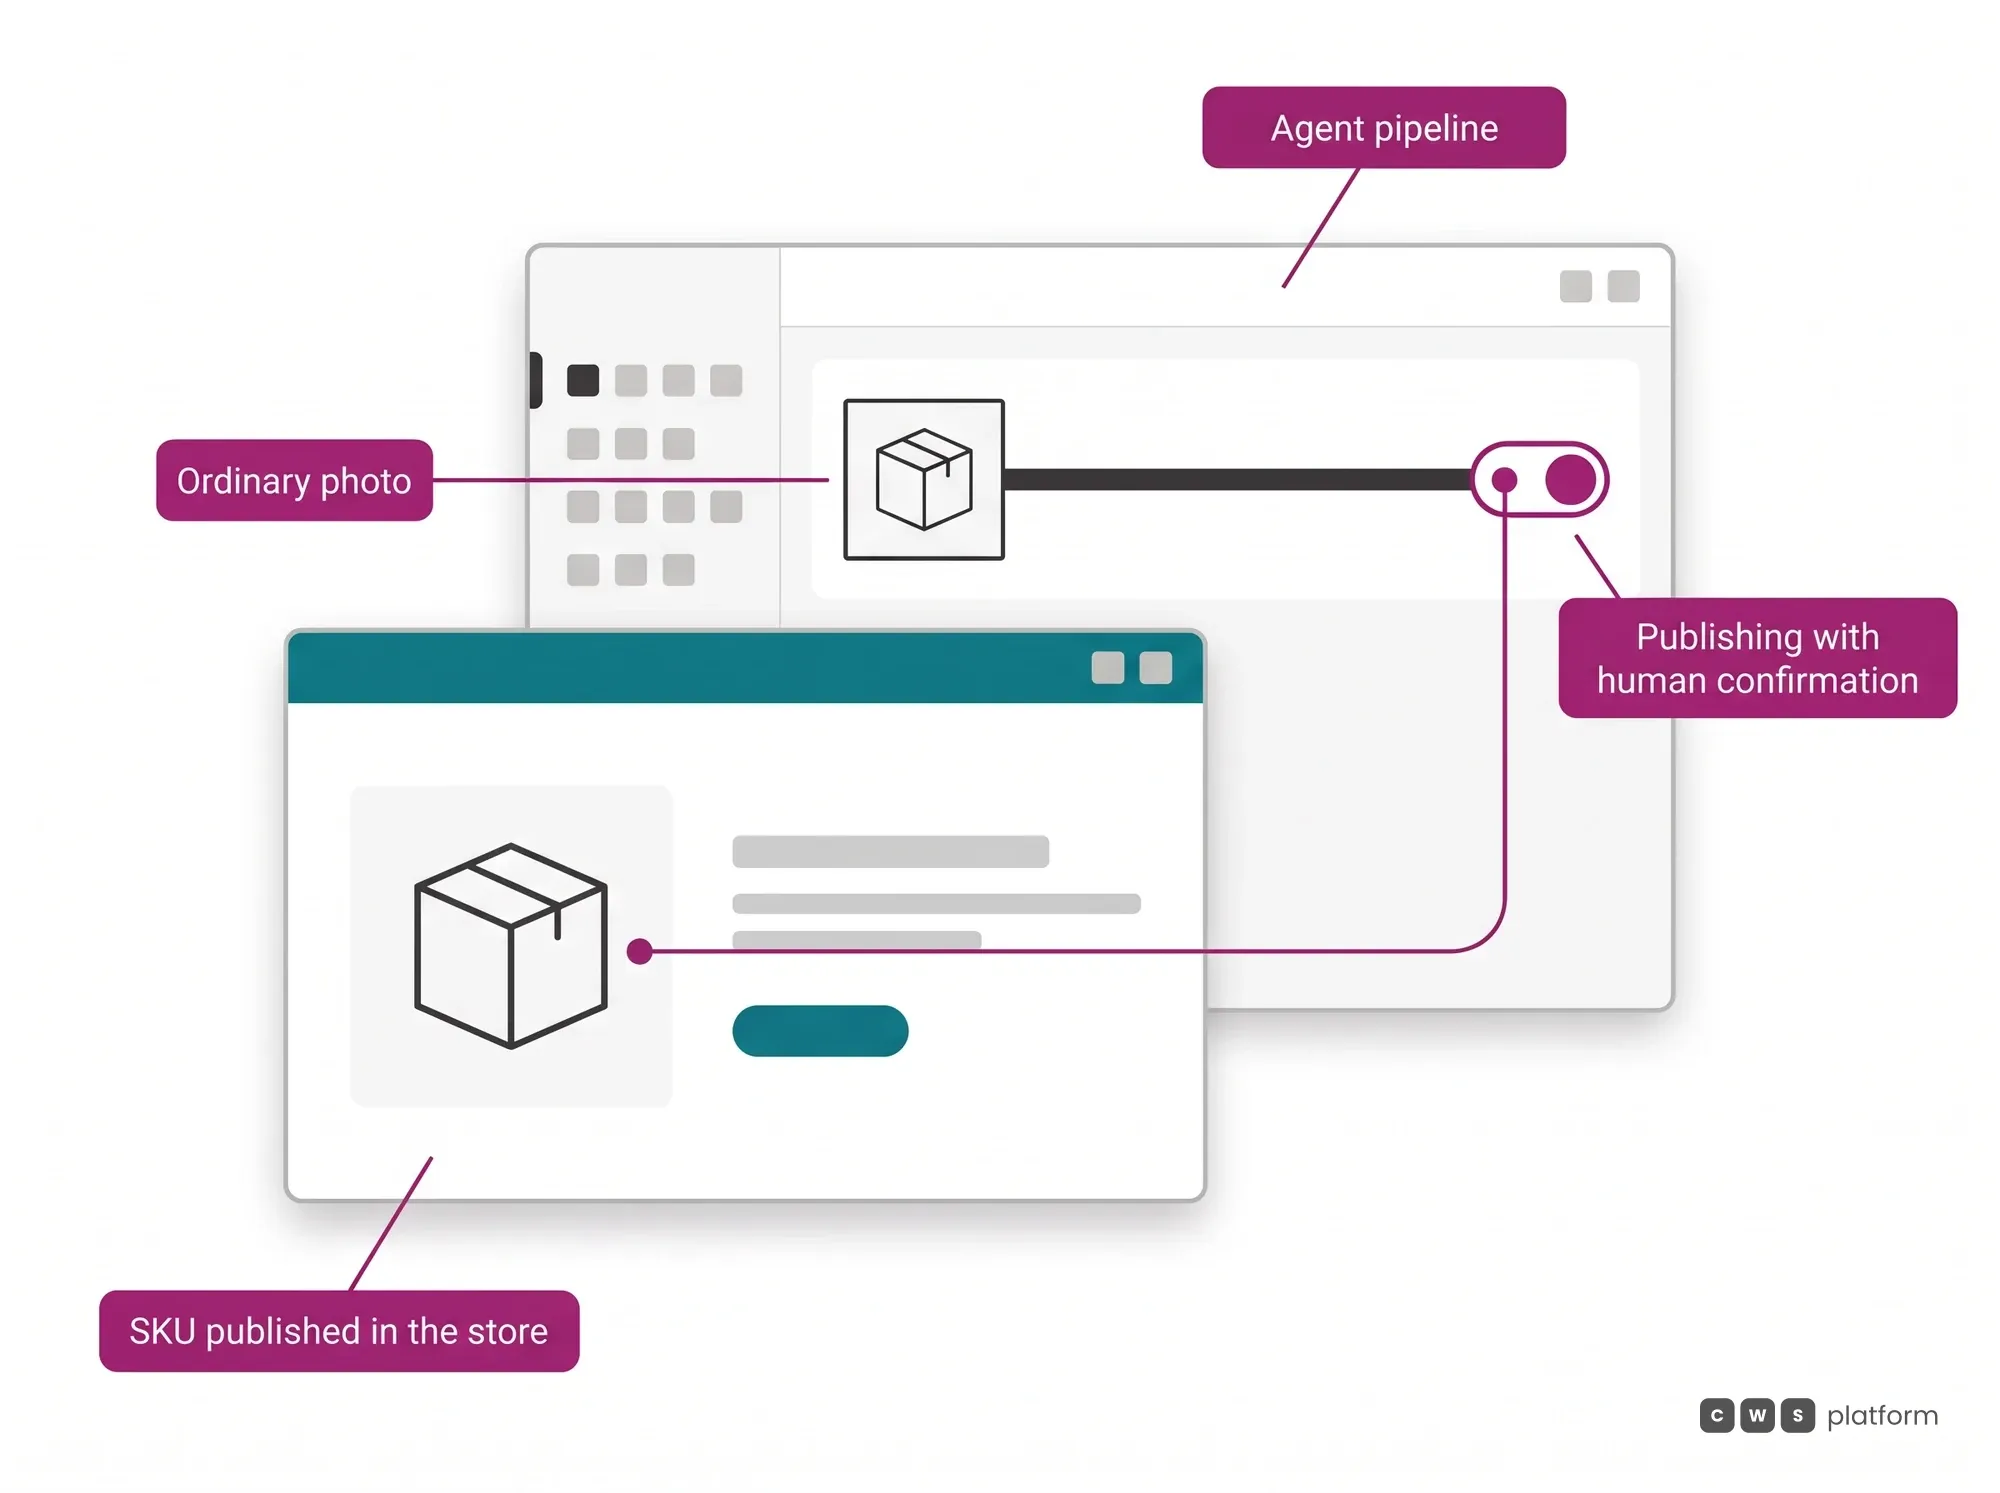
The agent that turns an ordinary photo into a catalog item ready to sell. The pipeline has 7 steps, from photo to publication per SKU, running through professional image, product record and publication into Product Catalog & MDM. It is the agent that attacks the entry bottleneck: catalog onboarding at scale, which otherwise consumes weeks of manual work and delays everything else in the project.
The capability no one replicates
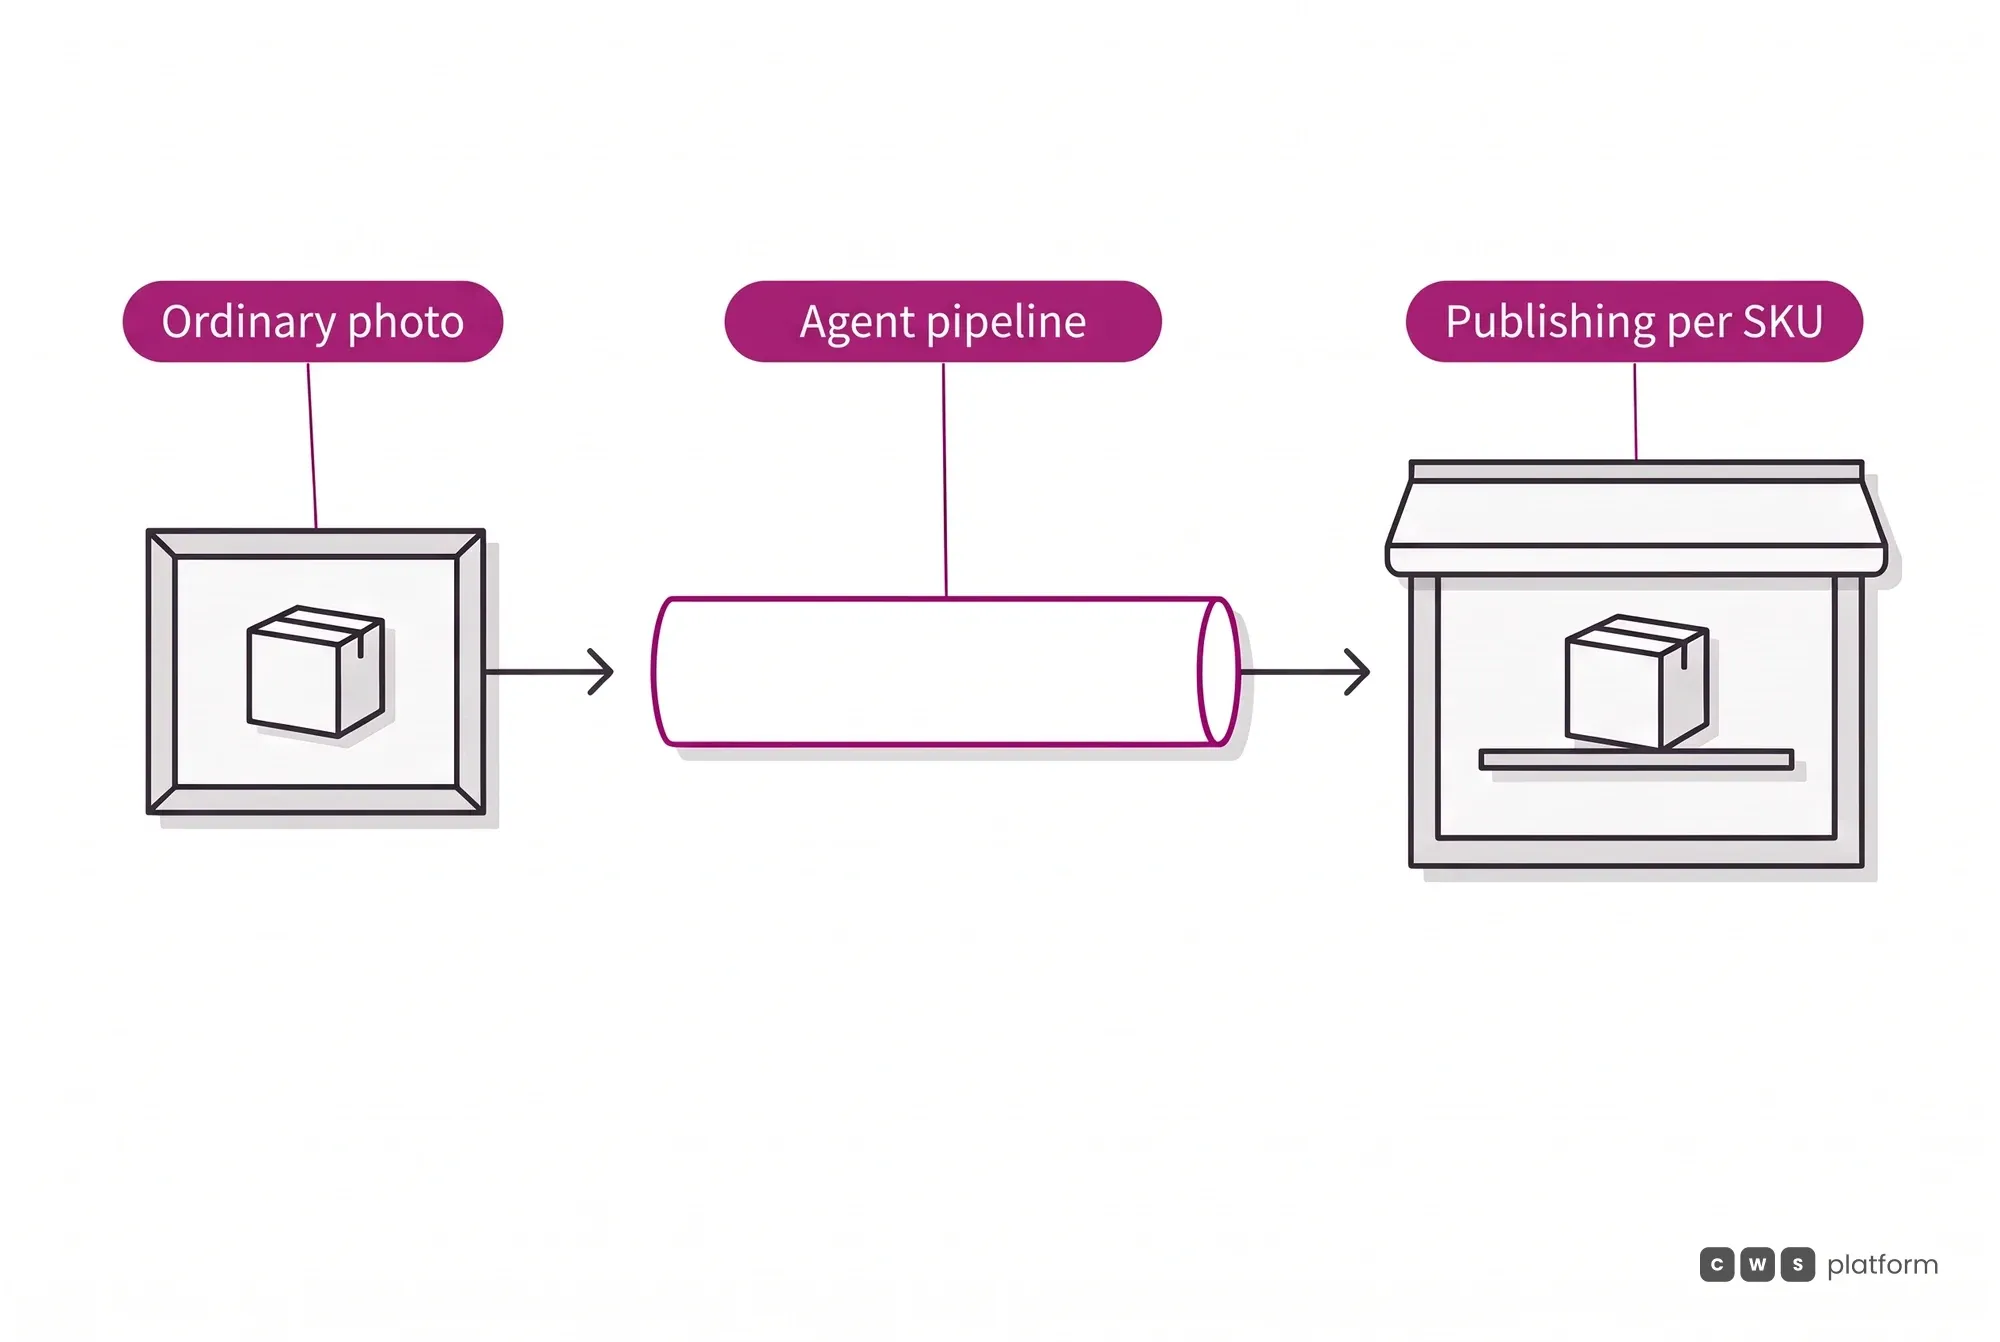
The counter photo becomes a catalog image, with no studio
Treated background, standardized framing, and the same presentation for the cheap item and the expensive one. The gain is not aesthetic: a catalog with inconsistent visual standards teaches the buyer to distrust whatever looks amateur, and they distrust the item, not the photo. Standardizing presentation is what lets thousands of SKUs share one storefront without dragging each other down.
A pipeline per SKU, not a batch that passes or fails
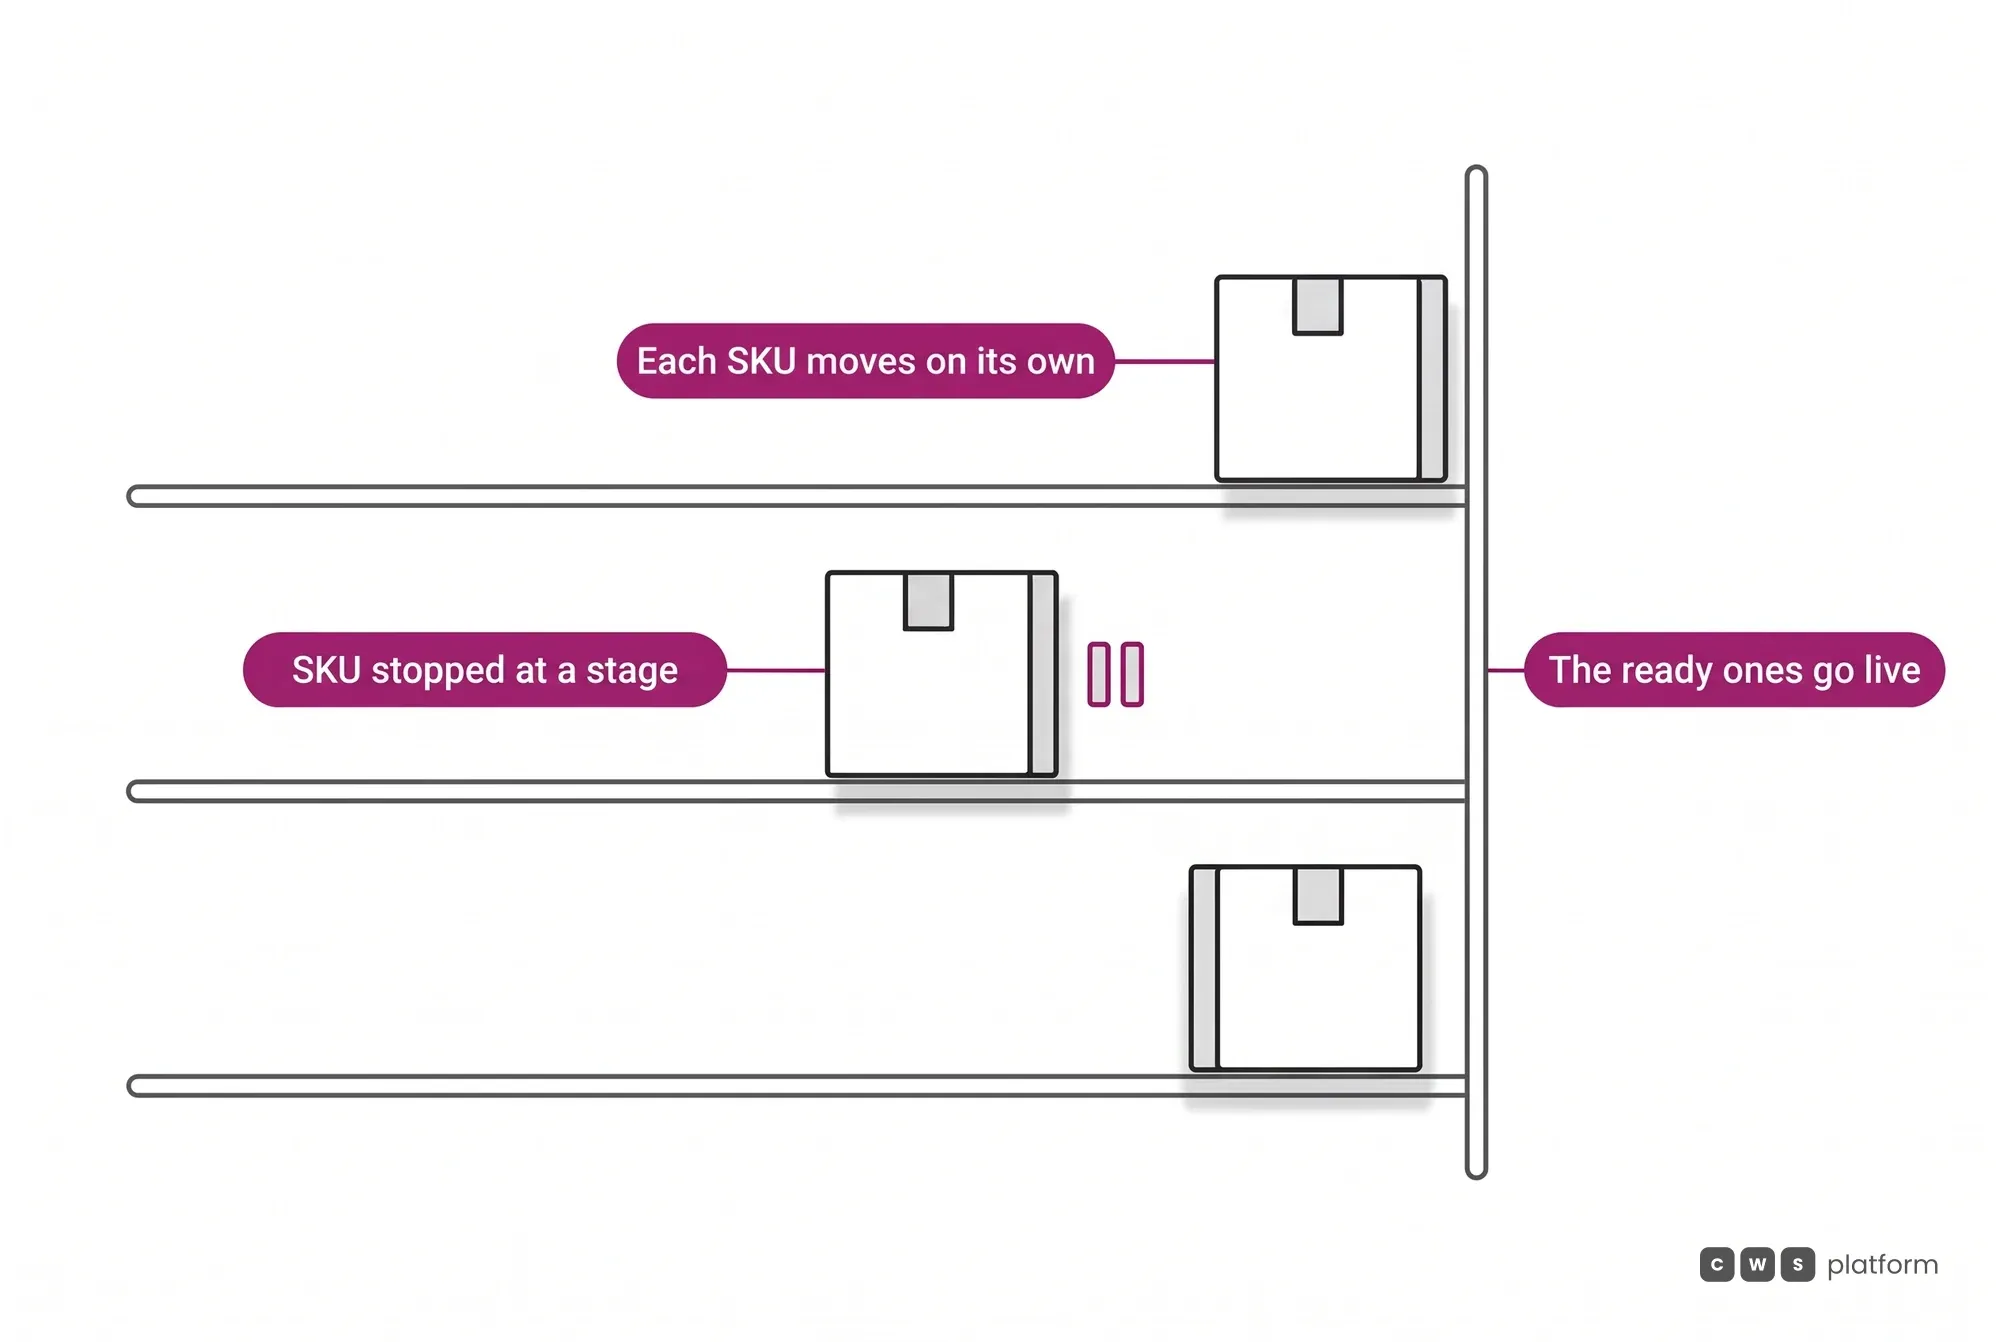
The 7 steps run item by item, so the catalog reaches production while it is still being enriched, rather than after the last photo is done. A SKU stuck at one step is one SKU stopped, not an entire load stopped. For an operation that has to launch with the catalog live, that difference decides whether the project delivers in waves or waits for the end.
The 7 steps, and where the human comes in
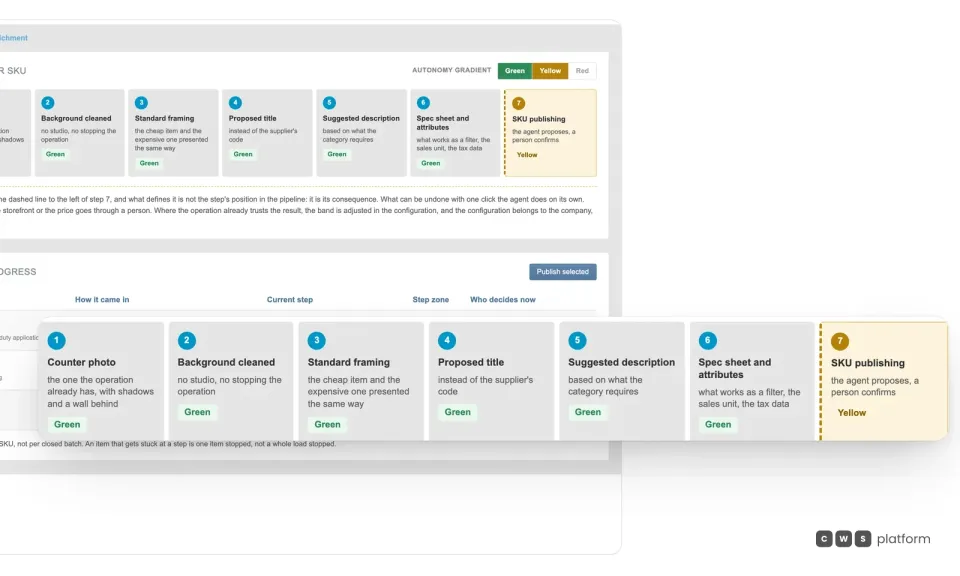
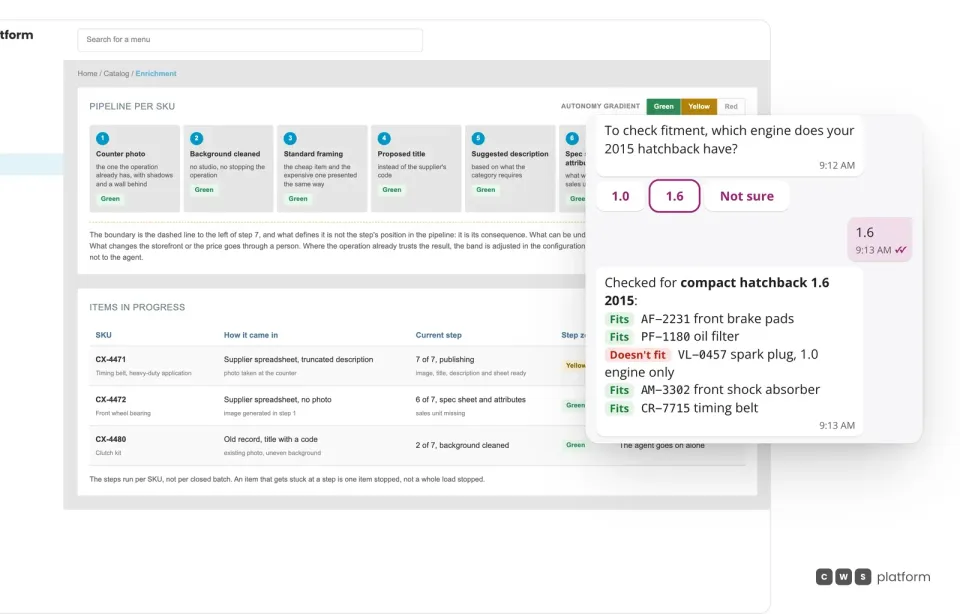
Generating an image with AI and proposing a title and description are reversible, low-risk actions, so they run on their own: that is the green zone of the Autonomy Gradient. Publishing the product changes what the buyer sees, so publication is the step where the agent proposes and the human confirms. The rule deciding this is not the step's position in the pipeline, it is the step's consequence: what a click undoes, the agent does; what changes the storefront or the price goes through a person. Where the operation already trusts the output, the zone is adjusted in configuration, and the configuration belongs to the company, not to the agent.
Per-SKU pipeline
Six steps the agent does alone. The seventh, publishing, goes through a person.
The Catalog Enrichment Agent handles photo, background, framing, title, description and spec sheet in the green zone; publishing the SKU changes the storefront, so it stays in the yellow zone, where it proposes and a person confirms.
At scale: one SKU, many contexts
The same base asset yields more than one output. From the approved photo, the agent generates the product across different scenes and formats, which makes context a decision for whoever is selling: a catalog by store type, by region or by buyer profile, and the format each channel demands of the same product. Because the image is born attached to the SKU, the batch can be regenerated when the season changes, and one correction propagates to every place that image appeared.
Headquarters isn't the only producer. The same pipeline serves the field, on a phone, within the library and templates the brand approved, with human review where the risk calls for it.
From photo to fitment: the data that puts the right product in front of the buyer
Selling by chat depends on reliable technical data: size, standard, unit of sale and, in the aftermarket, the vehicle a part fits. Parts fitment is the hardest case, and the messiest. Manufacturers record OEM part numbers without a prefix, without zeros or with a dot in the middle. The same model is classified five different ways. The automaker's name changes from one manufacturer to the next. That breaks spreadsheet lookups and simple automation.
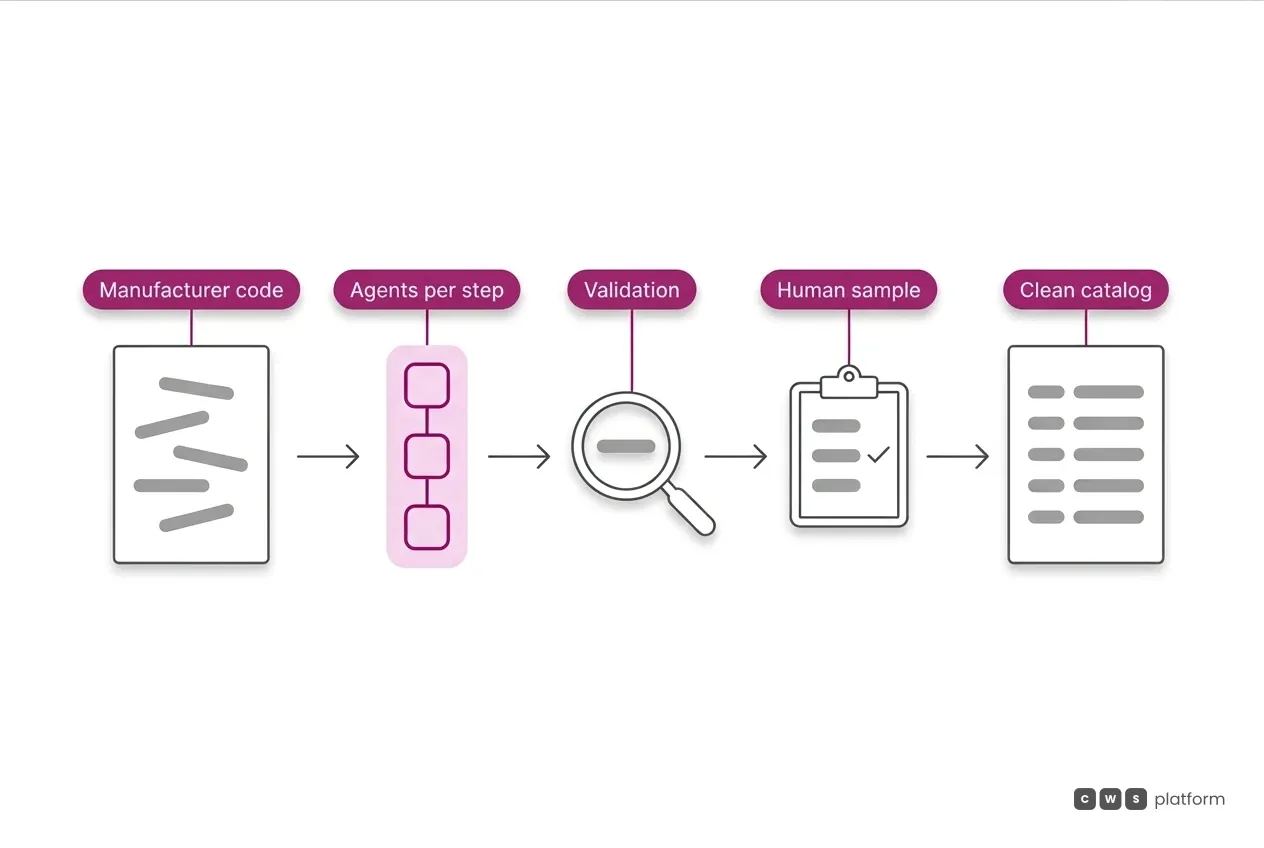
The Catalog Enrichment Agent processes this data with specialized agents, one per step. One coordinates the work and goes back a step when it finds a gap. Another validates each result with exact-term and semantic search, reranking and a knowledge graph. Where there is nothing to reason about, plain code runs; AI comes in only where thinking is needed. And it does not make things up: fitment without a year from the manufacturer is left out. At the end, validation is human, by statistical sampling. The same method applies to other technical catalog data, such as sizes, standards and units of sale.
27 days instead of 21 months.
19 manufacturers, 1.83 million fitment rows and 45,052 SKUs, with human audit on every manufacturer.
736,320 fitment records in 30 hours,
for a manufacturer that had none; 579,064 validated by the agents before human review.
97% accuracy in 54 minutes,
on a messy 43-page PDF with 14,040 items.
CWS Platform measurements on aftermarket customer projects, 2026.
This is the data the Sales Copilot checks when a buyer asks, in chat, whether an item matches what they need.
In operation
Circuito de Compras (CDC) · apparel wholesale in Brás, São Paulo
Inside MayaApp CDC, the white-label app that serves merchants in five languages and accepts international payments, a CWS Platform AI agent runs product cataloging and curation. This is a qualitative case by release decision: we tell the mechanism and the reach, not numbers. The agent's personification, including the name merchants call it by, is the customer's decision and not the platform's.
Read the Circuito de Compras case →Frequently asked questions
Do I need a photo studio to use the pipeline?
No, and that is the agent's starting point. It was built for the photo the operation already has: the one taken at the counter, with shadows and a wall in the background. The pipeline treats the background, standardizes the framing and returns a presentable image matching the rest of the catalog. Where studio photography already exists it enters the same flow; what the agent solves is the case where it does not exist and will never exist for thousands of items.
What happens when it gets a SKU record wrong?
The error stays in the step before publication, which is where it costs little. Generating the image, proposing a title and suggesting a description are reversible actions, so they run on their own; publishing the SKU changes what the buyer sees, so it goes through human confirmation. Correcting before publishing is routine review. The order of the steps exists so that the error always falls on the cheap side of that line.
Can it handle a catalog with thousands of items?
That is exactly the problem it exists for. The 7 steps run per SKU rather than per closed batch, so the catalog goes live in waves: finished items publish while the rest is still being enriched. An item stuck at one step is one item stopped, not an entire load stopped, and the operation does not wait for the last SKU to open the store.
Can the AI record the wrong fitment?
It can make mistakes, which is why it never publishes on its own. Every batch goes through sample-based validation, split by product line, year and part number; if the sample fails, the whole batch goes back. And the agent never fills in what the manufacturer did not provide: fitment without a year is left out.